Weengineerintelligence,notjustwrappers.
Our dedicated pods integrate directly with your existing infrastructure, delivering production-ready AI microservices, secure data pipelines, and scalable GPU clusters.
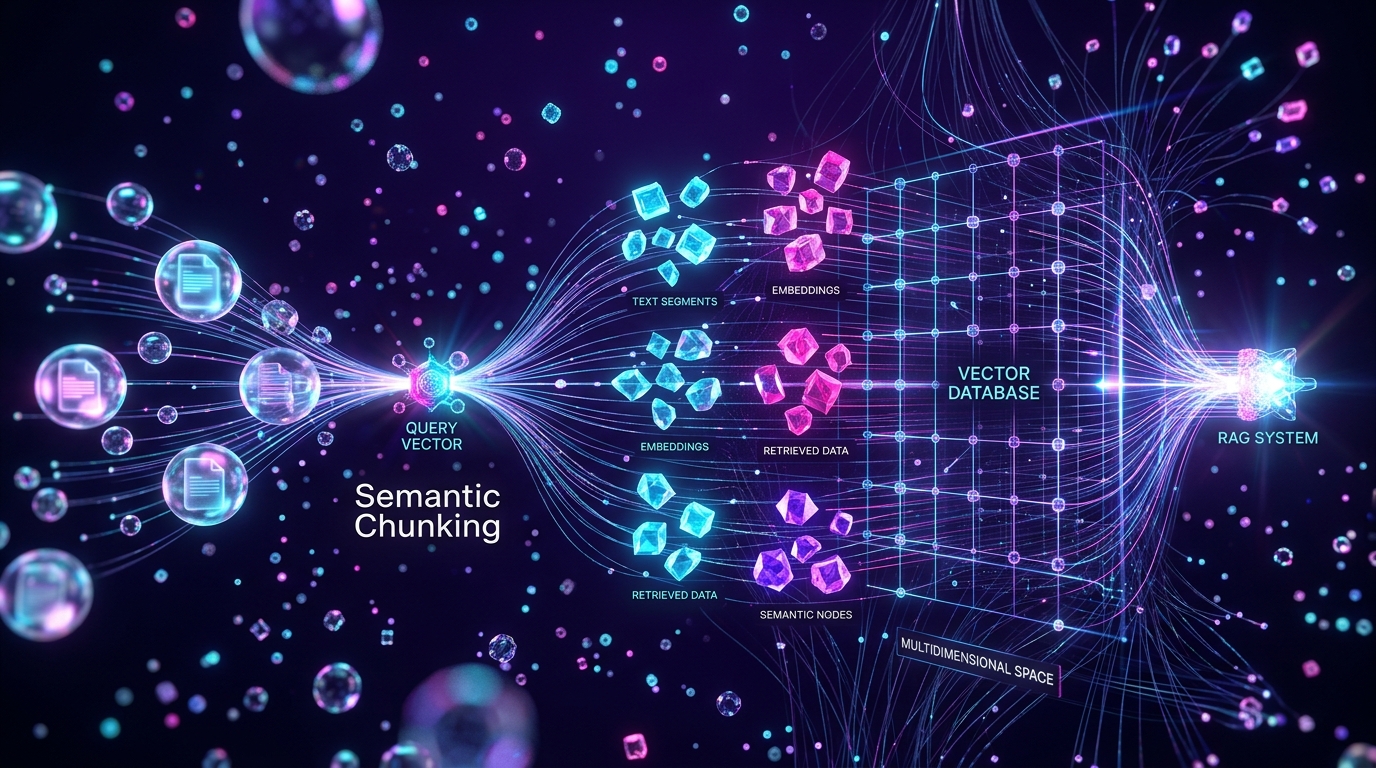
RAG Pipelines
Enterprise-grade Retrieval-Augmented Generation. We build chunking strategies, embedding pipelines, and semantic search clusters.
Autonomous Agents
Multi-agent orchestration systems capable of executing complex, multi-step workflows without human intervention.
Cloud Migration & Architecture
Migrating legacy on-premises systems to the cloud, building scalable software architectures, and implementing modern DevOps practices.
Scalable Inference
Zero-downtime model serving and autoscaling for production LLM workloads. From cold start to 10k RPS without infra headaches.
ETL & Data Engineering
High-throughput data ingestion pipelines processing millions of rows into vector databases daily.
Security & Compliance
SOC2-compliant infrastructure ensuring your proprietary data never leaks into public foundation models.
Full-Stack AI Matrix
The modern stack we use to build enterprise-grade intelligent systems.
LLM Integration
Custom RAG pipelines, fine-tuning, and prompt engineering using OpenAI, Anthropic, and open-source models.
Data Engineering
High-throughput ETL pipelines, vector databases (Pinecone, Weaviate), and structured data extraction.
Autonomous Agents
Multi-agent systems using LangChain, AutoGen, and custom orchestration for complex workflows.
API & Deployment
Purpose-built AI APIs and deployment pipelines. We ship scalable microservices using FastAPI, Modal, and Docker.